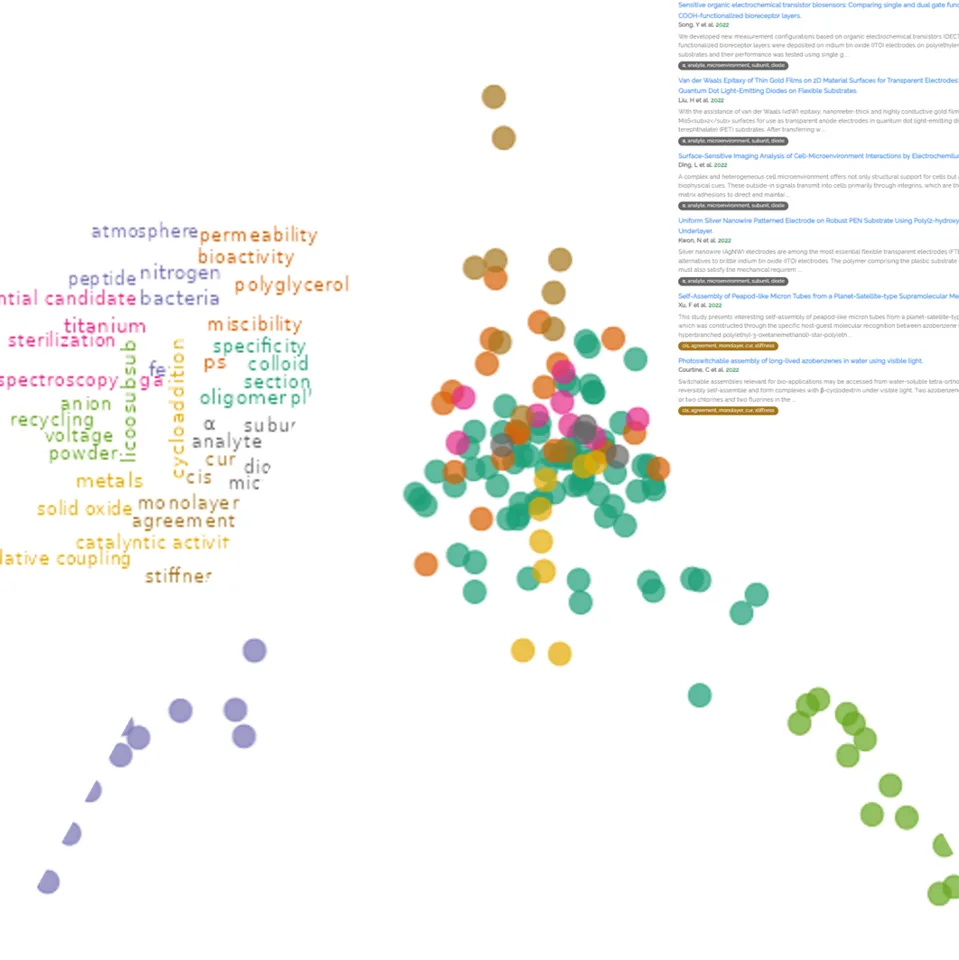
smartlyt (opens in a new tab) is an R Shiny app that clusters the results of a PubMed search.
The problem
A literature search on a chemical or topic returns hundreds of papers. The usual process is to pick a few at random, follow their references, accept and reject, and start over. Every time you gain traction you hit a tangent and lose hours. A short list of relevant papers up front saves time, and the client’s budget.
The approach
smartlyt queries PubMed, weights the terms in each abstract with term frequency-inverse document frequency (TF-IDF), and groups documents with hierarchical clustering. It is one of the simpler ways to cluster documents, and it works well enough to give you starting points.
Next steps
- Make it faster.
- Compare against topic models such as Latent Dirichlet Allocation.
- Use citation networks to find papers that cite each other.
My JavaScript is limited, so help improving the interface is welcome. Nearly all of my projects are open to collaboration; get in touch.